Performance
Cocoa and ADCIRC were benchmarked on a large hurricane hindcast, with strong scaling in CPU-MPI mode and single-GPU runs on three GPU generations.
Benchmark Configuration
The benchmark is a 25-day Hurricane Katrina (2005) hindcast on a 1,568,749-node mesh, forced by a tidal boundary, tidal potential, and hurricane wind and pressure fields. Both models run the implicit and explicit (lumped-mass) solvers at a 2 s time step.
ADCIRC runs use double precision throughout. Cocoa computes in double precision with single-precision storage for bandwidth-bound fields.
Hardware:
CPU (PSC Bridges-2): dual-socket AMD EPYC 7742 64-core nodes (128 cores per node), 128 to 1024 MPI ranks (1 to 8 nodes)
GPU (Lambda Labs): NVIDIA H100 (SXM5, host Intel Platinum 8480+) and NVIDIA B200 (SXM6, host Intel Platinum 8592+), single device
GPU (workstation): NVIDIA V100 (host AMD Ryzen 9 9950X), single device
The implicit and explicit solvers do different work per step, so their results are reported separately.
Note
The single-node, scaling and single-GPU results on this page were measured
in June 2026, before the first tagged release (0.4.2). They predate
element sorting for GPU memory locality (Element Ordering), the
0.6.0 multi-GPU work described under Multi-GPU Runs, and the 0.6.0
change of the default wetting test to ADCIRC’s linear form. They show
the relative standing of the two models; the current release’s timings
differ.
Implicit Solver Results
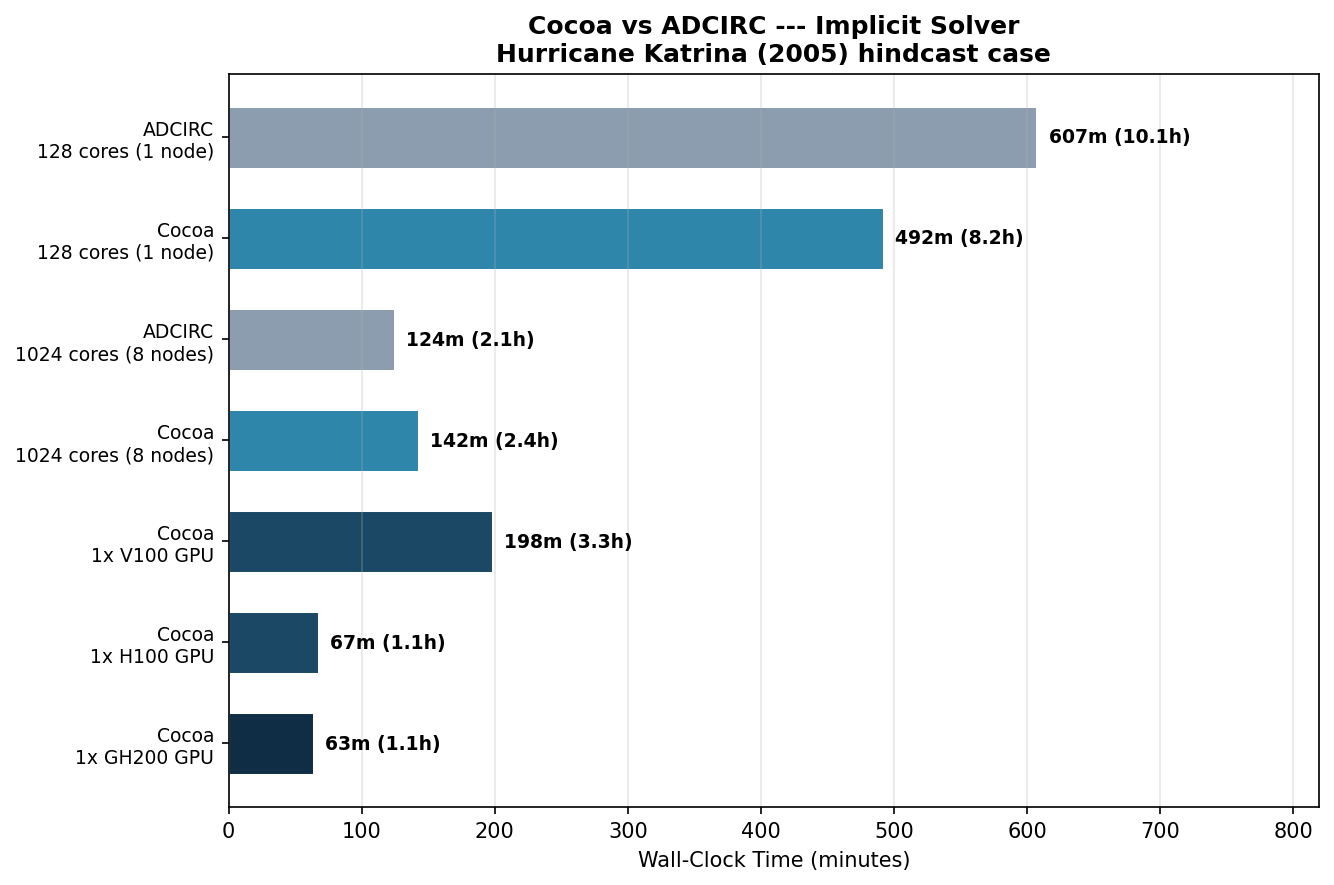
Fig. 14 Wall-clock time for the implicit solver (dt=2s) on the 1.57M-node Hurricane Katrina hindcast.
Model |
Hardware |
Wall Time |
|---|---|---|
ADCIRC |
128 cores (1 node) |
607m (10.1h) |
Cocoa |
128 cores (1 node) |
492m (8.2h) |
ADCIRC |
1024 cores (8 nodes) |
124m (2.1h) |
Cocoa |
1024 cores (8 nodes) |
142m (2.4h) |
Cocoa |
1x V100 GPU |
207m (3.5h) |
Cocoa |
1x H100 GPU |
82m (1.4h) |
Cocoa |
1x B200 GPU |
62m (1.0h) |
Explicit Solver Results
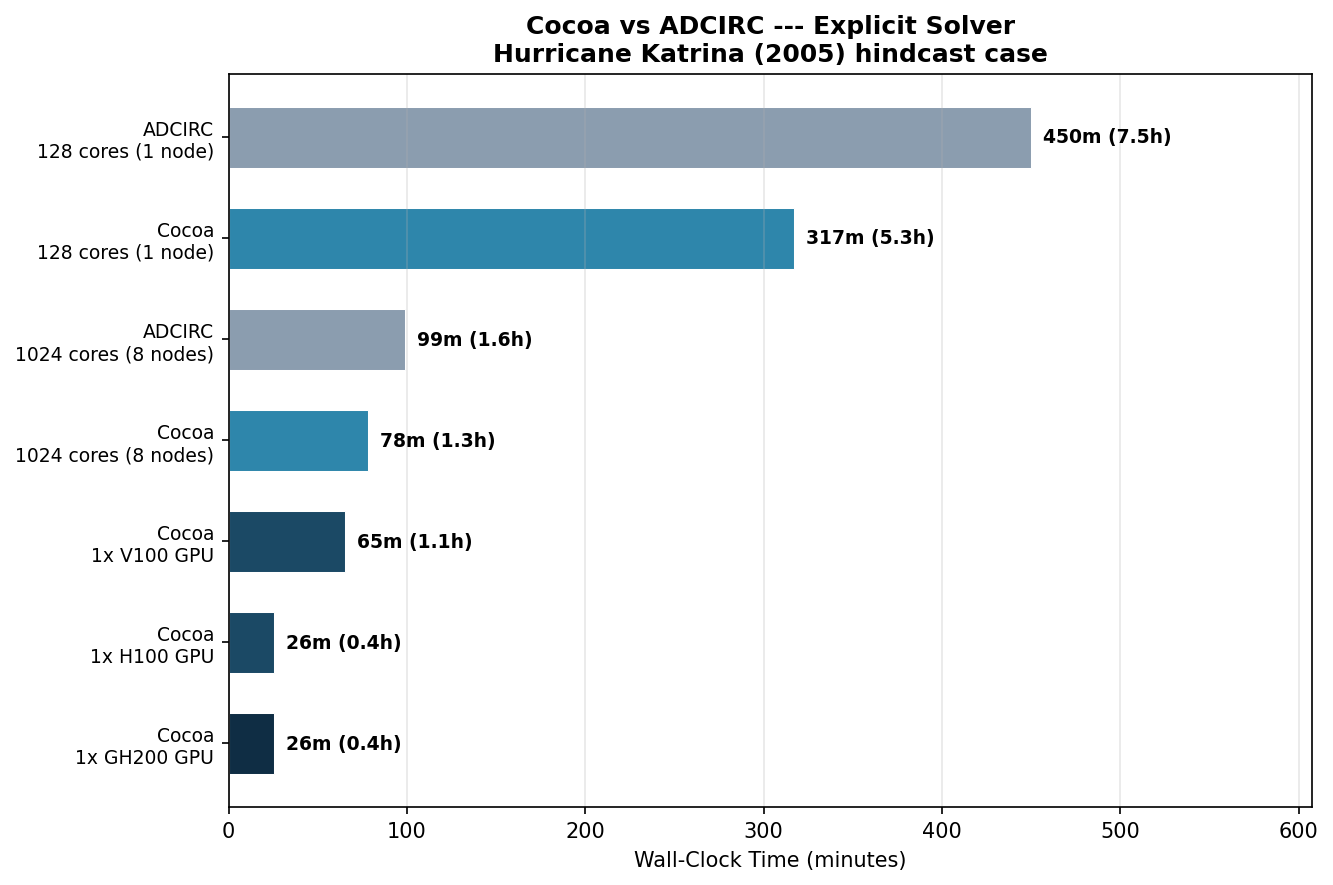
Fig. 15 Wall-clock time for the explicit lumped-mass solver (dt=2s) on the 1.57M-node Hurricane Katrina hindcast.
Model |
Hardware |
Wall Time |
|---|---|---|
ADCIRC |
128 cores (1 node) |
450m (7.5h) |
Cocoa |
128 cores (1 node) |
317m (5.3h) |
ADCIRC |
1024 cores (8 nodes) |
99m (1.6h) |
Cocoa |
1024 cores (8 nodes) |
78m (1.3h) |
Cocoa |
1x V100 GPU |
72m (1.2h) |
Cocoa |
1x H100 GPU |
35m (0.6h) |
Cocoa |
1x B200 GPU |
34m (0.6h) |
CPU-MPI Scaling
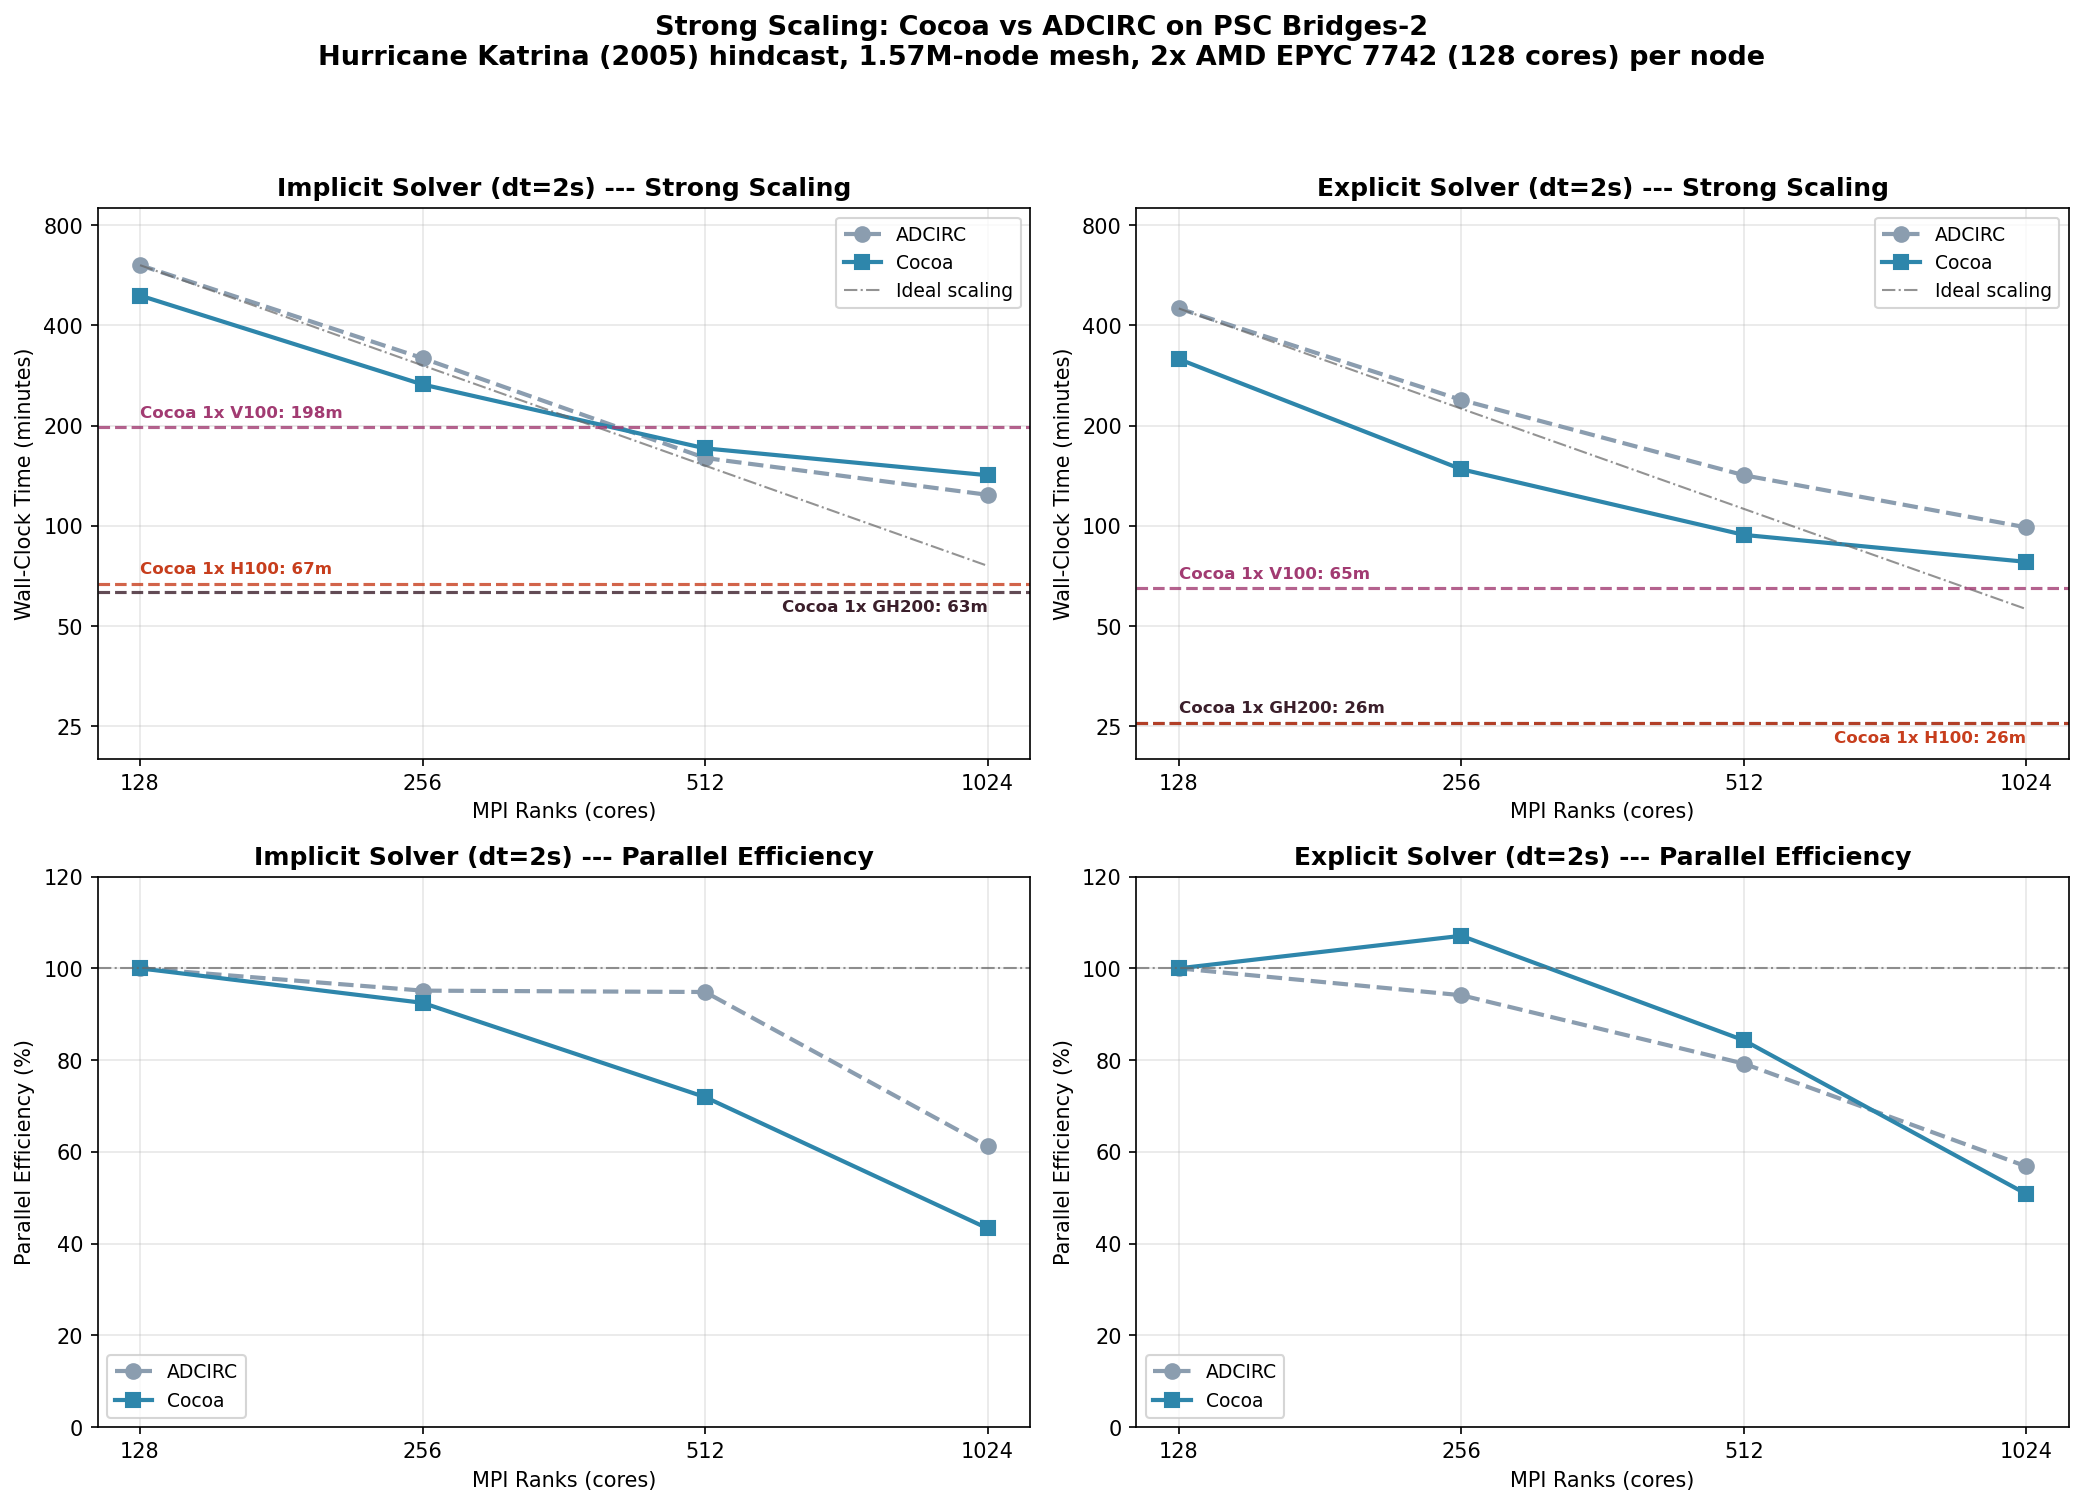
Fig. 16 Top: log-log scaling of wall-clock time vs MPI ranks on PSC Bridges-2, one panel per solver, with horizontal reference lines marking Cocoa’s single-GPU wall times for the same solver. Bottom: parallel efficiency relative to each configuration’s own 128-core run.
Wall-clock time in minutes by MPI rank count:
Ranks |
Cocoa Implicit |
ADCIRC Implicit |
Cocoa Explicit |
ADCIRC Explicit |
|---|---|---|---|---|
128 |
492 |
607 |
317 |
450 |
256 |
266 |
319 |
148 |
239 |
512 |
171 |
160 |
94 |
142 |
1024 |
142 |
124 |
78 |
99 |
Multi-GPU Runs
Each step of a multi-GPU run waits for the slowest GPU, so two inputs matter as much as the hardware: a mesh whose elements are sorted for GPU memory locality (see Element Ordering), and a partition that balances the wet nodes as well as the elements (see Balancing Wet Work). Together they keep two GPUs within about 2% of each other on the global STOFS mesh.
With both, a 6 h global STOFS run (12.8M nodes) with the implicit solver on two H100 GPUs takes 87.1 s in Cocoa 0.6.0, against 111.1 s in earlier releases.
Triangle-Only Meshes
Quadrilateral support costs nothing on a mesh with no quadrilaterals: no quadrilateral tables are allocated and no quadrilateral kernel is launched. On the 12.8M-node global STOFS mesh, a triangle-only run was 0.2% faster per step than the same run before quadrilateral support was added.