Numerical Methods
Spatial Discretization
Finite Element Mesh
Cocoa uses unstructured meshes of linear (P1) triangles [Hughes2000] [Zienkiewicz2013], optionally mixed with bilinear (Q1) quadrilaterals (Quadrilateral Elements):
Nodes located at element vertices
Linear (bilinear) interpolation within elements
Continuous across element boundaries
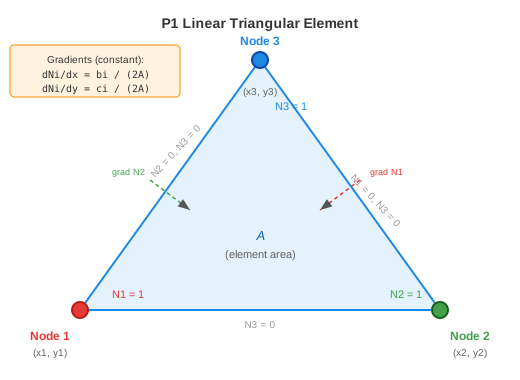
Fig. 45 A P1 linear triangular element. Each shape function Ni equals 1 at its own node and 0 at the other two. Gradients are constant within the element.
Shape Functions
For a triangle with vertices \((x_1, y_1), (x_2, y_2), (x_3, y_3)\), the linear shape functions are:
where \(A\) is the element area and, with \((i, j, k)\) a cyclic permutation of \((1, 2, 3)\),
\(b_i\) and \(a_i\) are ADCIRC’s FDX and FDY, the names the GWCE and quadrilateral sections use as well.
Shape function gradients:
Mass Matrix
Cocoa has consistent and lumped mass matrices. The consistent element mass matrix for linear triangular elements is:
The factor \(A/12\) arises from integrating the product of linear shape functions over the element. The off-diagonal entries couple neighboring nodes, which makes it more accurate than the lumped form.
The lumped mass matrix diagonalizes the mass matrix by row-summing:
The lumped formulation enables an explicit direct solve (no iterative solver needed) at the cost of some spatial accuracy. The GWCE-specific mass matrix formulation including \(\tau_0\) weighting is given in Equation (12). See Configuration for solver selection.
Quadrilateral Elements
Cocoa also runs on bilinear (Q1) quadrilaterals [Hughes2000]
[Zienkiewicz2013], and on hybrid meshes mixing triangles and quadrilaterals
in a single partition. At startup Cocoa evaluates each element’s area, Green
coefficients and scale factors and stores its corners; the assembly kernels
integrate the element operators below from those corners each time they need
them (see the storage paragraph). Both element types share the code: the
reference element (cubature points and weights, basis values and reference
gradients) is built once from Intrepid2 [Bochev2012] through
geometry/ReferenceElement.{hpp,cpp}, the element evaluation is
geometry/ElementGeometry.hpp (one body, run by the host table fill, by the
device recompute of a rotated mesh, and by the assembly kernels that integrate
the operators), and the uploaded device storage is
geometry/ElementTables.hpp. Only
ReferenceElement.cpp includes Intrepid2; the tags take their topology keys
from Shards’ own header, and everything past the reference element sees plain
fixed-size arrays.
Corners \(p_i = (x_i, y_i)\), \(i = 0..3\), are stored counter-clockwise with cyclic indices (mod 4) in the same projected coordinates the triangle uses.
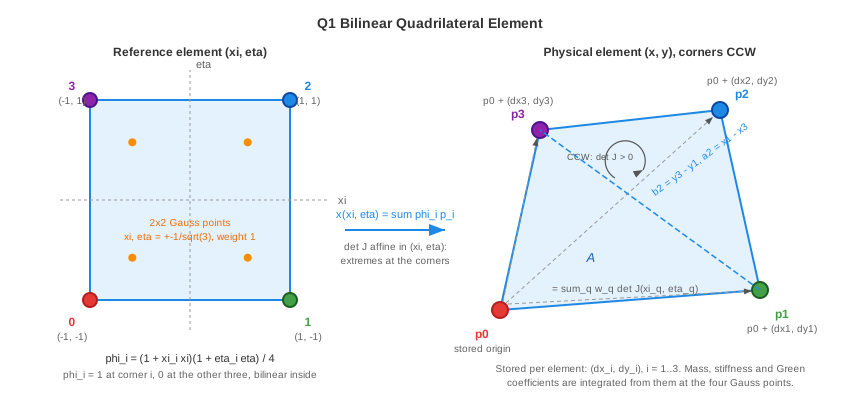
Fig. 46 A Q1 bilinear quadrilateral. Left: the reference square, corners at \((\xi_i, \eta_i) = (\pm 1, \pm 1)\) numbered counter-clockwise from \((-1, -1)\), with the four Gauss points at \(\pm 1/\sqrt{3}\). Right: the physical element the bilinear map produces, its corners stored as offsets from corner 0, the chord \(p_1 p_3\) whose components are corner 2’s Green coefficients, and the counter-clockwise orientation that keeps \(\det J\) positive.
Green coefficients. The quadrilateral analogue of ADCIRC’s FDX/FDY is
so that \(b_i/(2A)\) and \(a_i/(2A)\) are the exact area-averaged
\(x\)- and \(y\)-derivatives of basis function \(i\), the same
role the triangle’s \(b_i = y_j - y_k\), \(a_i = x_k - x_j\) play
there. At three vertices Equation (27) reduces identically to the
triangle formula: Geometry::green_coefficients is templated on the
element-type tag so a test can pin that reduction exactly (no tolerance) against the
classical triangle spelling, and a second test pins both instantiations against the basis gradients
Intrepid2 integrates. The construction
identities checked at \(10^{-12}\) on random convex quadrilaterals are
\(\sum_i b_i = \sum_i a_i = 0\), \(\sum_i b_i x_i = \sum_i a_i y_i =
2A\), \(\sum_i b_i y_i = \sum_i a_i x_i = 0\), and for any field linear in
\((x, y)\), \(\sum_i f_i b_i / (2A)\) recovers \(\partial f/
\partial x\) exactly (and the \(a_i\) analogue for \(y\)). Every
ADCIRC term of the form “element-averaged forcing times the gradient of a
test function” carries over from the triangle unchanged, with \(N = 4\)
and the nodal mean \(\tfrac{1}{4}\sum_i\) in place of the triangle’s
\(\tfrac{1}{3}\sum_i\).
Bilinear reference map. With reference coordinates \((\xi, \eta) \in [-1, 1]^2\) and corner signs \((\xi_i, \eta_i) = (-1,-1), (1,-1), (1,1), (-1,1)\):
with \(\partial x/\partial\xi = \sum_i x_i\, \partial\phi_i/\partial\xi\) and so on, and \(|J| > 0\) everywhere on a convex, counter-clockwise quadrilateral. The physical gradients follow from the standard isoparametric inverse-Jacobian relations.
2x2 Gauss integration and why full, not reduced. The element operators have no closed form on a general straight-sided quadrilateral (unlike the triangle’s area-only formulas), so the kernels integrate them numerically from the element’s corners:
at the four points \((\pm 1/\sqrt{3}, \pm 1/\sqrt{3})\) with unit weights. The mass integrand is bilinear on a straight-sided quadrilateral, so 2x2 Gauss is exact for \(M\) and for every identity the tests check; \(K^{xx}\) and \(K^{yy}\) are exact on parallelograms and a converged approximation otherwise. One-point (reduced) integration at the centroid is not used: a bilinear quadrilateral under one-point quadrature has a spurious zero-energy deformation mode (the Q1 “hourglass” mode, a strain field that vanishes at the centroid but not elsewhere), and suppressing it needs an hourglass-control term [Flanagan1981] with no counterpart in the triangle path or in the GWCE gravity-wave operator. Full integration avoids the problem at the cost of four cubature points per operator entry.
Construction-level identities checked at \(10^{-12}\) on random convex quadrilaterals: \(\sum_{ij} M_{ij} = A\); \(M\) symmetric with every entry positive; the row sums of \(K^{xx}\) and \(K^{yy}\) are zero (the constant, or rigid, mode carries no gravity-wave energy); \(K^{xx}, K^{yy}\) symmetric positive semi-definite; \((K^{xx} x)_i = b_i/2\) and \((K^{yy} y)_i = a_i/2\) exactly (the integrand is polynomial); \((K^{xx} y)_i = (K^{yy} x)_i = 0\). On a rectangle \(a \times b\) the operators reduce to the closed forms
checked at \(10^{-14}\), invariant under rotation and translation of the rectangle.
Storage: the corners, not the operators. Nothing about a quadrilateral’s
operators is stored. The table keeps the element’s three corner offsets
relative to corner 0 (6 doubles, 48 bytes), and each kernel integrates from
them what its thread owns. A thread that owns one matrix row integrates that
row (Geometry::element_operator_row): 4 entries each of \(M\),
\(K^{xx}\) and \(K^{yy}\), 12 doubles out of 6 loads. A thread that
owns a whole element (the GWCE right-hand side, the lumped diagonal, the
lumping weights of the nodal accumulators) integrates the whole element once
(Geometry::element_operators), because integrating a row at a time would
repeat the Jacobian and the physical gradients once per vertex; measured, that
cost the right-hand side 34% against integrating the element once. Storing the
three packed symmetric operators and the lumped rows would take 34 doubles,
272 bytes per quadrilateral, the largest dependent load chain in the assembly
kernels, while the arithmetic that replaces them (about 400 flops per element)
is not what those kernels are short of. The whole-element form returns the
operators in packed symmetric layout: the 10 upper-triangle entries of a
\(4\times4\) operator in the row-major order
\((0,0), (0,1), (0,2), (0,3), (1,1), (1,2), (1,3), (2,2), (2,3), (3,3)\)
(Geometry::packed_index).
A row from element_operator_row exactly equals the same row of the
whole-element operators, with no tolerance: a row accumulates
over the same cubature points in the same order out of the same Jacobian, and
IEEE multiplication commutes exactly, so the entry below the diagonal that the
packed form holds as
\(\phi_j\phi_i\) is the same double as the \(\phi_i\phi_j\) the row
forms. A unit test pins every entry of every row against the whole element’s
operators with an exact comparison.
The identity holds wherever the compiler does not fuse a multiply-add. A fused term is rounded once where a separate multiply and add round twice, and which terms a compiler fuses depends on what it inlined and vectorized around them, so two loop shapes over the same arithmetic can differ in the last bit on any FMA target: a GPU build, where the operators are formed by the device compiler inside the assembly kernels, and equally an FMA host. What holds everywhere is the bound the mechanism predicts, one saved rounding per fused term. The exact-match gate rests on a single toolchain generating and comparing its own integration references.
The same operators serve all three GWCE time levels: the LHS gravity-wave term (coefficient \(a_{00}\)) and both RHS gradient terms (\(b_{00}\), \(c_{00}\)) integrate the identical \(K^{xx}\), \(K^{yy}\) for a given quadrilateral. There is no separate operator per time level, unlike the mass-matrix pattern which does depend on solver type (Lumped vs Consistent Mass Matrix).
Lumped mass and nodal averages. The lumped row \(ML_i = \sum_j M_{ij} = \int_\Omega \phi_i \, d\Omega\) (exactly \(A/4\) on a parallelogram) plays the quadrilateral’s role in the lumped solver and in every “area times value” nodal accumulator (the lumping convention). The quadrilateral element average of a nodal field is the plain nodal mean \(\tfrac{1}{4}\sum_i f_i\), the triangle’s \(\tfrac{1}{3}\sum_i f_i\) with \(N = 4\).
Conditioning: corners relative to corner 0. Absolute projected
coordinates run to \(10^6\)-\(10^7\) m while an element edge is
\(O(10^2)\) m; the shoelace area and the Gauss sums above difference
pairs of such coordinates, which loses about six decimal digits if done on
the raw absolute values (measured 2e-6 relative error in area at
\(10^6\) m production offsets, degrading the identities above from
\(10^{-12}\) to \(10^{-10}\)). Every sum that would otherwise
difference two absolute coordinates instead translates the four corners so
corner 0 becomes exactly \((0,0)\) first
(Geometry::corners_relative_to_first); every other corner is then one
subtraction of two nearby doubles, which is exact. Area and both element
operators are translation-invariant, so this changes nothing mathematically.
The Green coefficients (Equation (27)) need no such translation:
each one is already a single subtraction of two nearby coordinates.
The wet/dry corner rules a quadrilateral needs beyond the geometry above (its dry corners are not always edge neighbors of its wet ones, unlike a triangle’s) are Quadrilateral Rules (W1, DE1) in Wetting and Drying.
Temporal Discretization
Time Integration Scheme
Cocoa uses a three-level scheme for the GWCE:
This provides second-order accuracy in time.
The momentum equations average the pressure gradient over \(\zeta^n\) and \(\zeta^{n+1}\) (both known once the GWCE is solved), weight bottom friction and Coriolis by Crank-Nicolson, and treat advection and lateral stress explicitly (Momentum Equations).
Linear Solver
Assembly Pattern: Scatter-to-Gather
Every assembly in the CG solver (the GWCE right-hand side, the lumped
diagonal, the momentum right-hand sides and the consistent GWCE matrix) is
an element-parallel scatter: a thread evaluates one wet element’s rows and
adds them to the node-indexed target with Kokkos::atomic_add, three rows
for a triangle and four for a quadrilateral. Where the target is the sparse
matrix the two element types reach it differently. The triangle path hands
each row to sumIntoValues, which finds every column by a search along the
CSR row; the quadrilateral path resolves the column position of each of its
sixteen entries once at startup, so a thread per (element, row) adds straight
into the value array. Elements that touch ghost nodes add into the rank’s
overlap rows; one exchange after the scatter sums those rows into their
owners (sum_into_owned for vectors; for the matrix, the ghost rows are
held apart from the owned matrix and a plan built once adds them into the
owners’ rows). The open-boundary column elimination runs before the exchange,
on every row the rank assembled, because only the rank that computed an entry
knows its column is a boundary column; the per-row fix-ups (pinning boundary
and dry rows) run on owned rows only, after the exchange
(consistent matrix lifecycle).
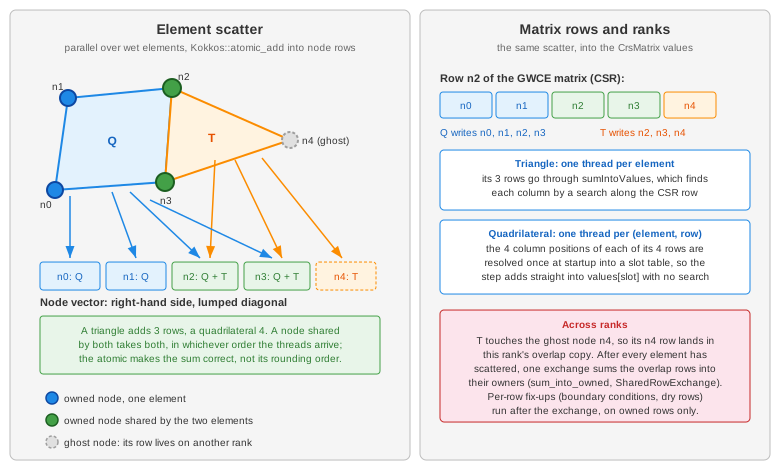
Fig. 47 A quadrilateral and a triangle that share an edge scatter into the same node rows: the two shared nodes receive both elements’ contributions, the ghost node’s row is summed into its owning rank by the export. The matrix panel shows the one place the element types differ, the row search of the triangle path against the precomputed slot of the quadrilateral path.
System Assembly
With the consistent mass matrix the GWCE produces a sparse linear system (the default lumped solver has a diagonal matrix and divides directly):
The matrix \(\mathbf{A}\) has the sparsity pattern of the mesh connectivity (see the GWCE discretization in Equation (12) and (13)).
Iterative Solver
Cocoa uses the Conjugate Gradient (CG) method via the Belos solver package from Trilinos [Heroux2005] [Bavier2012]:
Preconditioning
Jacobi preconditioning is applied:
Convergence Criteria
The solver terminates when the scaled residual norm satisfies the tolerance.
By default, Cocoa scales the residual by the initial residual norm
(NormOfInitialResidual):
with default tolerance \(\epsilon = 10^{-5}\).
The convergence scaling is selectable; the three available options are:
NormOfInitialResidual(default): \(\|\mathbf{r}_k\| / \|\mathbf{r}_0\| < \epsilon\)NormOfPrecInitRes: \(\|\mathbf{M}^{-1}\mathbf{r}_k\| / \|\mathbf{M}^{-1}\mathbf{r}_0\| < \epsilon\)None: \(\|\mathbf{r}_k\| < \epsilon\) (absolute tolerance)
Numerical Stability
CFL Condition
The Courant-Friedrichs-Lewy (CFL) condition guides the choice of a stable explicit time step:
where \(h_e\) is the element size and \(C \approx 0.5\) is the Courant number. Cocoa does not enforce it: it checks only that the configured time step is positive and never computes a CFL-limited step, so choosing a stable \(\Delta t\) is up to the user.
Floating-Point Precision
Cocoa performs all arithmetic in double precision (FP64). Both the lumped (explicit) and consistent (implicit) GWCE solvers, the momentum solver, and all reductions accumulate in double; the consistent mass matrix in particular requires it to avoid overflow in the iterative solve.
Mixed-precision storage. To cut memory traffic without changing the numerics, a subset of bandwidth-sensitive fields is stored as single precision (float) and promoted to double when a kernel reads it:
the prognostic velocity and flux fields,
the bottom-friction and lateral-stress tensors,
a subset of static mesh geometry (element areas, the nodal scale factors, the element continuity and momentum scale factors, Coriolis and
tan_phi), the slope-limiter coefficients, and nodal attributes.
Bathymetry, the element-averaged bathymetry, the general element scale
factor, the quadrilateral corner offsets and the spatial gradient coefficients
(the a and b shape-function derivative arrays) remain double
precision, as do
water-surface elevation, the GWCE/momentum right-hand sides, the assembled
system matrices, and all accumulators.
The float/double conversions are confined to a single boundary at
the gather/scatter step (Cocoa::Types::promote reads float storage up to
double; Cocoa::Types::narrow writes a double result back to float).
promote is an exact no-op when the field is double-stored, so read sites
are written uniformly regardless of a field’s storage precision; narrow
always truncates and is used only at float storage boundaries. Because the
working arithmetic is unchanged, the only numerical effect is the ~1e-7
relative round-off incurred when a float-stored field is written and later
re-read.
Performance considerations. This scheme targets GPUs, where memory bandwidth is usually the limiting factor rather than double-precision throughput; storing the heavily-streamed fields as float reduces the bytes moved per timestep. CPU architectures see little benefit, as they already hide the extra bandwidth of full double-precision storage, but they are unaffected because compute precision is identical in both cases.