Parallel Execution
This guide covers serial execution, shared-memory parallelism via OpenMP/CUDA/HIP, and distributed-memory parallelism via MPI.
Execution Modes Overview
Cocoa can be run in several configurations:
Mode |
Description |
|---|---|
Serial |
Single CPU thread, useful for debugging and small meshes |
OpenMP |
Shared-memory parallelism using CPU threads |
CUDA |
NVIDIA GPU acceleration |
HIP |
AMD GPU acceleration |
MPI |
Distributed-memory parallelism across multiple compute nodes |
MPI + GPU |
Distributed parallelism with GPU acceleration on each rank |
Serial Execution
For serial execution, run the cocoa executable directly:
./cocoa -i simulation.yaml
This is useful for:
Debugging numerical issues
Small test cases
Systems without MPI or GPU support
OpenMP Parallelism
When Cocoa is compiled with OpenMP support via Kokkos, you can control the number
of threads using the --kokkos-num-threads option:
./cocoa -i simulation.yaml --kokkos-num-threads=8
Alternatively, use the OMP_NUM_THREADS environment variable:
export OMP_NUM_THREADS=8
./cocoa -i simulation.yaml
At present the OpenMP backend is generally slower than the same simulation run with the serial execution space plus MPI: the OpenMP code uses atomics, which the serial-plus-MPI path avoids.
GPU Execution
For GPU builds (CUDA or HIP), Cocoa automatically uses the default GPU device. To select a specific GPU:
# Using Kokkos option
./cocoa -i simulation.yaml --kokkos-device-id=0

# Or using environment variable (CUDA)
export CUDA_VISIBLE_DEVICES=0
./cocoa -i simulation.yaml
MPI Distributed Parallelism
For large-scale simulations, Cocoa supports distributed-memory parallelism via MPI. This allows the mesh to be partitioned across multiple compute nodes, with each MPI rank responsible for a subdomain of the mesh.
A partitioned run reproduces the serial run up to round-off from summing in a different order. Every value a rank reads at a partition cut is combined over the ranks that share it first: ghost nodes take their owners’ values, each element-to-node wet/dry result is combined over all ranks (including at a cold start), lateral stress is summed over ranks before it is normalized, and the implicit solver eliminates open-boundary columns on the rank that computed each entry.
Fig. 8 Distributed execution model with ghost exchange between two MPI ranks
Requirements
Cocoa must be built with MPI support (Trilinos compiled with MPI enabled)
A partition file, which Cocoa creates on the first run if none exists (see Creating Partition Files)
Basic MPI Execution
To run with MPI:
mpirun -np 4 ./cocoa -i simulation.yaml --partition partition.nc
The --partition option specifies the partition file that defines how the mesh
is distributed across MPI ranks. If the file exists, it will be loaded. If it does
not exist, Cocoa will create it automatically using ParMETIS.
Note
On a GPU build, Cocoa runs the Kokkos host backend on one thread per rank.
Left at the default of one thread per core, those threads would compete
with the thread that launches the GPU kernels. Nothing needs to be passed
for this. --kokkos-num-threads=N or KOKKOS_NUM_THREADS overrides it.
Mesh Partitioning
Fig. 9 Mesh partitioning pipeline from input mesh to distributed execution
Cocoa uses ParMETIS (via Trilinos/Zoltan2) for mesh partitioning. The partitioner uses graph-based algorithms to minimize communication while balancing the computational load across MPI ranks.
Balancing Wet Work
By default the partition balances elements. Much of each time step works only
where there is water, so on a mesh with large dry areas one rank can hold most
of the wet nodes while another waits for it. mesh.partition.wet_balance balances the nodes that start wet
as well:
mesh:
  partition:
    wet_balance: initial_condition   # or none, or a level in metres
initial_conditionThe wet set the run starts from. A cold start applies the same rule as the circulation: wet where the total depth with the configured initial water level exceeds
physics.h0, and dry whereversurface_submergence_stateis 1. A restart reads the wet/dry state in the restart file.- a number
Ground below that level above the datum counts as wet.
none(default)Elements only.
The partition then gives each rank an even share of both the elements and the wet nodes, each within 1 % of the mean (the unweighted default allows 5 %). The tighter tolerance matters because the step alternates phases that each wait for the slowest rank: on global STOFS with two GPUs, 5 % left one rank 11 % heavier in owned nodes, which the solver’s every iteration waited on. It changes only the partition, so results move by round-off, as they do between any two rank counts.
Partition File Format
Partition files are stored in NetCDF format and contain:
Node coordinates (
node_x,node_y): Geographic coordinates of all nodesElement connectivity (
element_nodes): Element node indices, three columns on a triangle-only mesh and four on a hybrid one, where a triangle row’s unused fourth column carries the variable’s_FillValue(-1).utils/plot_partition.pyreads this fill-aware and draws each element as itself, triangle or quadrilateral.Node ownership (
node_owner): MPI rank that owns each nodeElement ownership (
element_owner): MPI rank that owns each elementPer-rank data: Each rank’s owned and ghost node ids and owned elements, which a run loads directly
Mesh id (
mesh_idglobal attribute): The fingerprint of the mesh the partition was built for (see Mesh Identification)Weighting (
partition_weightingglobal attribute): Thewet_balancerule the partition was balanced on (see Balancing Wet Work)
Automatic Partition Naming
When no explicit partition file is provided, Cocoa uses the naming convention:
<mesh_filename>.partition_<N>.nc
For example, with mesh.nc and 8 MPI ranks, the partition file would be:
mesh.nc.partition_8.nc
Creating Partition Files
Partition files can be created in two ways:
Automatic creation: When running with MPI and the partition file does not exist
Pre-computation: Using the
--create-partitionoption
Pre-computing Partitions
For large meshes, pre-compute the partition file before the production run so the run does not pay the partitioning overhead:
# Create a partition file for 8 subdomains
./cocoa -i simulation.yaml --create-partition 8
This will:
Read the mesh file specified in
simulation.yamlPartition the mesh into 8 subdomains using ParMETIS
Save the partition to
<mesh_filename>.partition_8.ncExit without running the simulation
To specify a custom output filename:
./cocoa -i simulation.yaml --create-partition 8 --partition my_partition.nc
Note
Creating partition files only requires serial execution. The partitioner will use MPI if available but works correctly with a single rank.
Partition Caching
Cocoa caches partition files to avoid re-partitioning on subsequent runs. The cache records the mesh id, which validates the partition against the current mesh. If the mesh changes in any way the id covers (coordinates, depth, connectivity or element order, boundaries, nodal attributes, SAL data), or the rank count differs, the cache does not match; Cocoa computes a new partition and writes it over the file.
A cache records the wet_balance rule it was built with in its
partition_weighting attribute. A run that asks for a different rule still
uses the cached partition, and logs a warning naming both rules; delete the
file to rebalance. Caches written before Cocoa 0.6.0 record no rule and are
reused without a warning.
To force regeneration of a partition file, delete the existing file:
rm mesh.nc.partition_8.nc
mpirun -np 8 ./cocoa -i simulation.yaml
Example Partition Visualization
The following image shows an example ParMETIS partition of a global ocean mesh (GSTOFS domain) with 256 subdomains. Each color represents a different MPI rank’s subdomain:
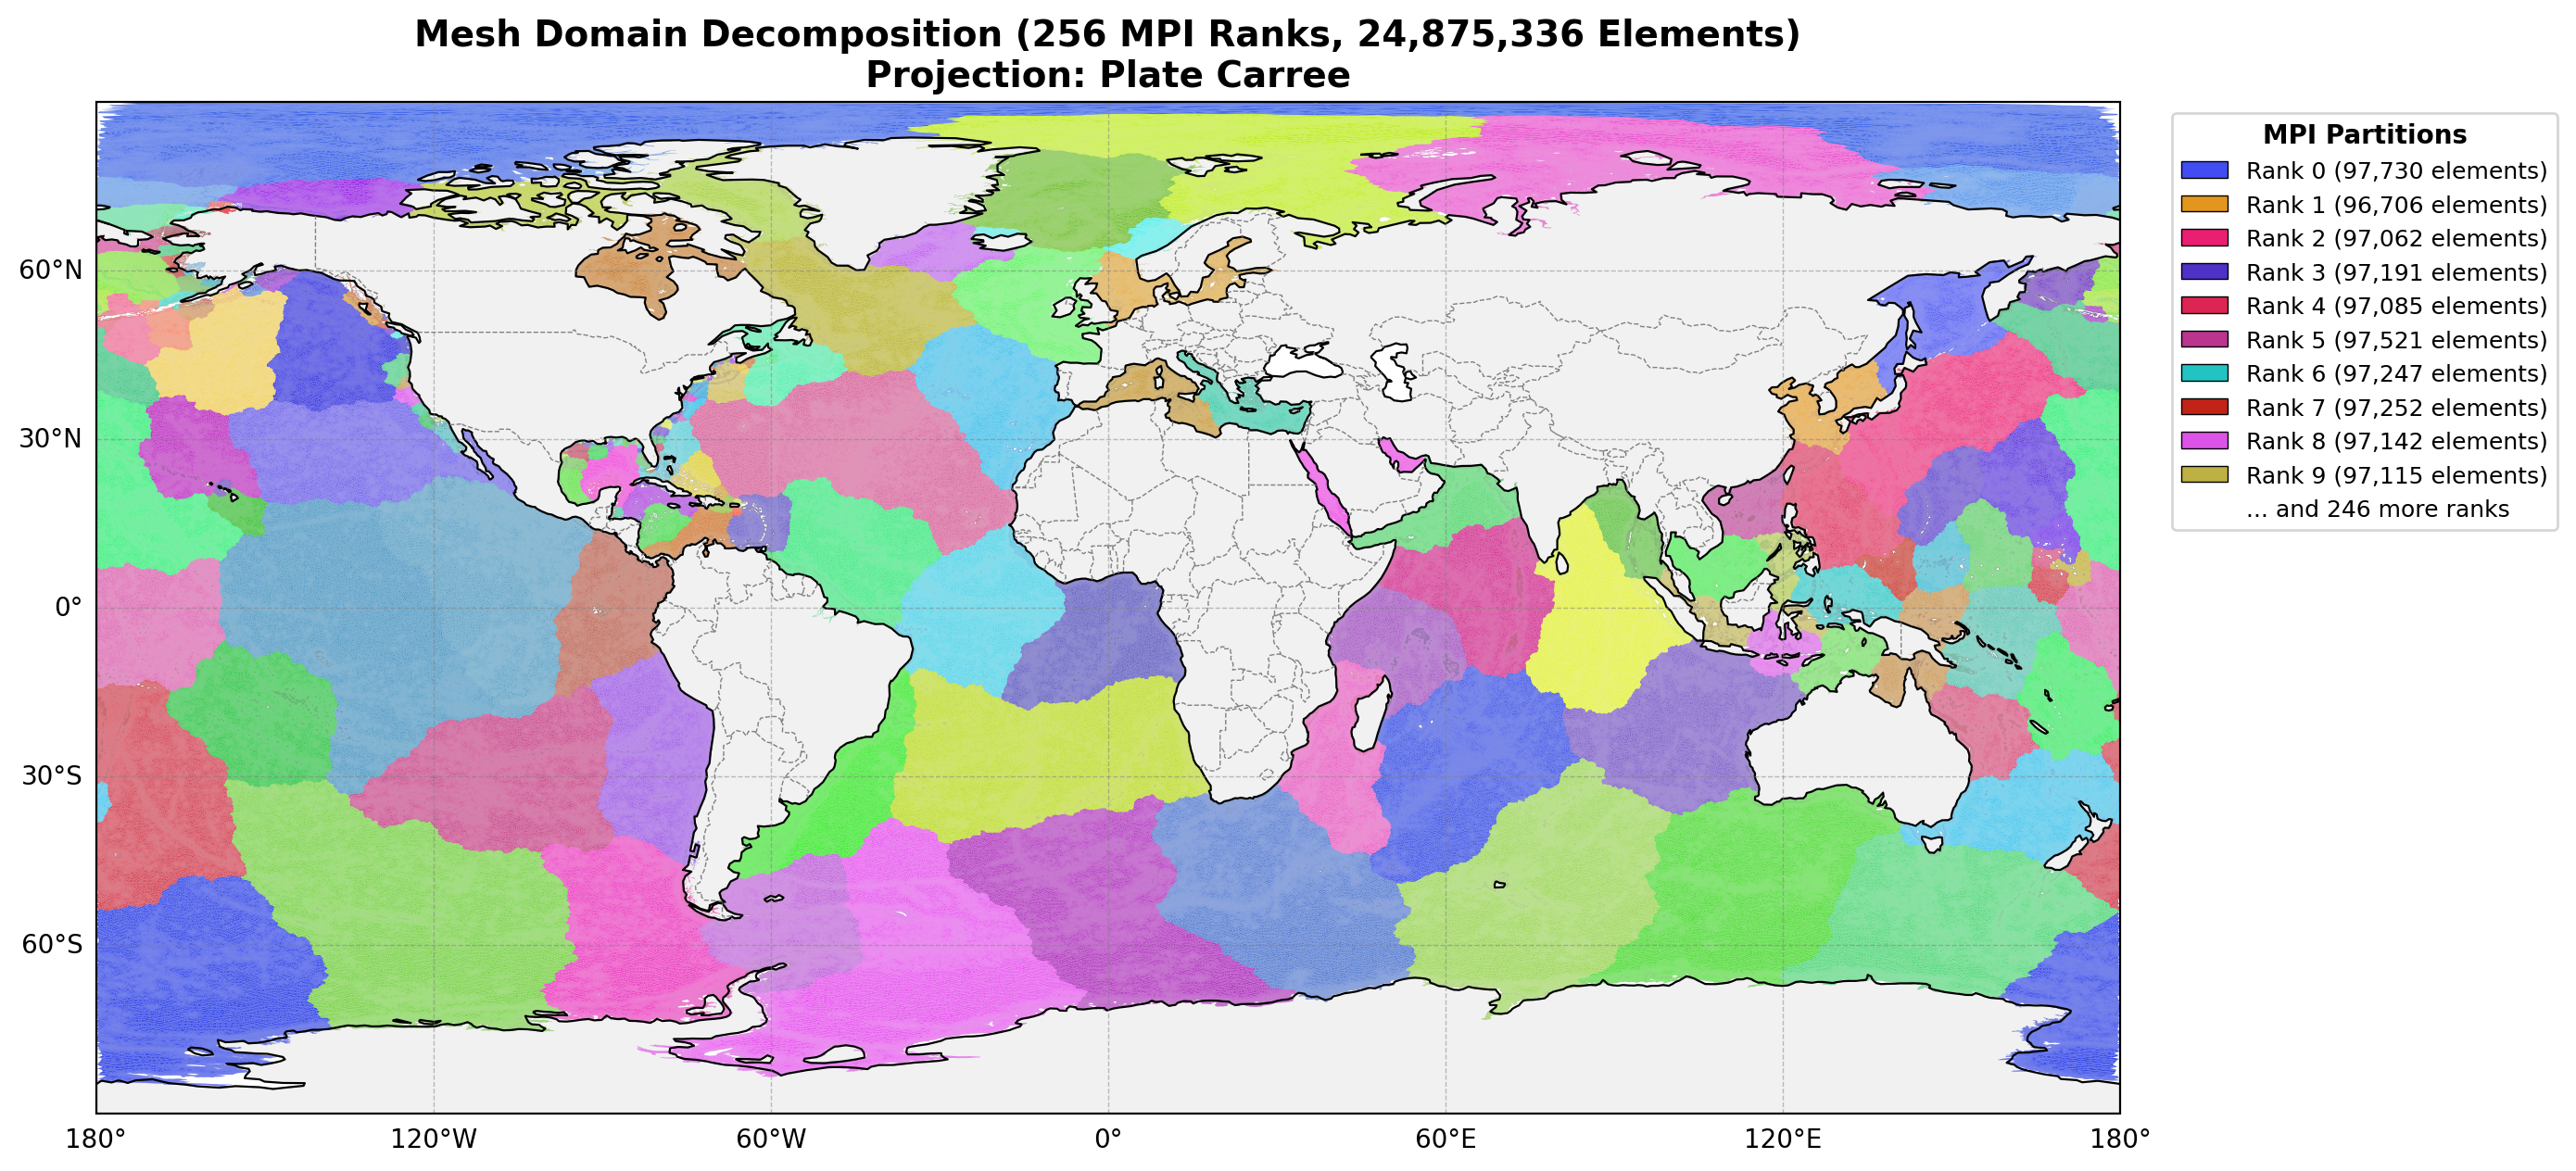
Fig. 10 Example mesh partition for a global ocean model. The mesh is divided into 256 subdomains
Internal Weir Pairs Across Partitions
ADCIRC requires that both sides of an internal weir boundary be assigned to the same MPI subdomain. This constraint simplifies the overflow computation (each rank has direct access to both pair elevations) but restricts the partitioner, potentially leading to load imbalance near weirs.
Cocoa removes this constraint entirely. Internal weir pair nodes may be owned by different MPI ranks because the ghost exchange mechanism already provides the necessary data.
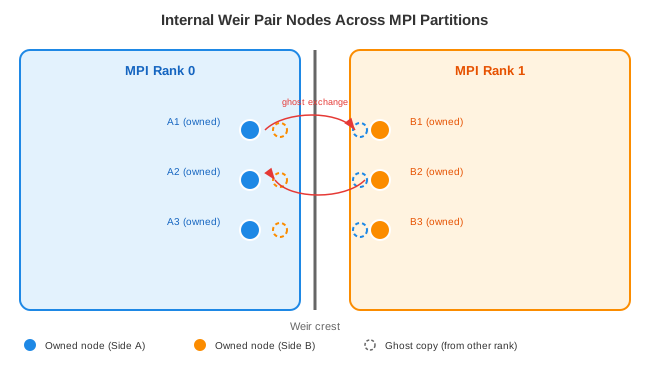
Fig. 11 Weir pair nodes on opposite sides of a partition boundary. Each rank holds ghost copies of the other rank’s nodes, with the same elevation and wet/dry status as their owners, so both ranks see the same pair state.
How it works:
Ghost layer inclusion: Pair nodes on the opposite side of a weir share elements near the crest, so they are automatically included in the ghost layer during mesh partitioning.
Consistent ghost copies: the GWCE solution reaches every ghost copy, and the wet/dry pass combines every element-to-node result over all ranks before reading it, so every copy of a node – weir pair nodes on other ranks included – leaves the pass with the same elevation (\(\zeta^{n+1}\)) and wet/dry status as its owner.
Independent computation: Each rank therefore has the elevation at both its owned boundary nodes and their pair nodes (as ghost copies). The overflow formula runs independently on each rank using local data. Since both sides of the weir are listed as boundary nodes in the mesh, both ranks compute their own QFORCE contributions.
Bounds-checked RHS application: When applying QFORCE to the GWCE RHS, boundary segments that span partition boundaries may have one endpoint that is a ghost node. The kernel skips writes to ghost nodes (via a bounds check against the owned RHS size), so each contribution is applied only by the rank that owns the node.
Runtime validation:
At startup, BoundaryProcessor verifies that all internal weir pair node IDs
are valid (not -1) in the local partition’s global-to-local map. If a pair node
is missing from the ghost layer, an error is logged. This would indicate a
partitioning bug since weir pair nodes should always be in the ghost set.
Command Line Reference
Cocoa Options
Option |
Description |
|---|---|
|
Input configuration file (YAML format). Required; the file must exist |
|
Use specified partition file. If file exists, load it; otherwise create it |
|
Create partition for N subdomains and exit (no simulation) |
|
Enable verbose logging (debug level) |
|
Show version information and exit |
|
Show help message |
Note
Under an MPI launcher, command-line errors and --help/--version
output are printed by rank 0 only (detected from the launcher’s rank
environment variables before MPI_Init); every rank still exits with
the same status code.
Kokkos Options
Option |
Description |
|---|---|
|
Number of threads for OpenMP execution |
|
GPU device ID to use (0-indexed) |
|
Map device ID by |
|
Enable Kokkos warning messages |
|
Show all Kokkos command line options |